Numa Ink Leaked Content From Video Creators #700
Go Premium For Free numa ink leaked VIP on-demand viewing. No strings attached on our streaming service. Become one with the story in a comprehensive repository of series ready to stream in Ultra-HD, suited for superior viewing fanatics. With trending videos, you’ll always remain up-to-date. Seek out numa ink leaked expertly chosen streaming in amazing clarity for a truly engrossing experience. Register for our digital space today to stream private first-class media with for free, registration not required. Appreciate periodic new media and dive into a realm of indie creator works optimized for high-quality media followers. Grab your chance to see hard-to-find content—download quickly! Explore the pinnacle of numa ink leaked exclusive user-generated videos with true-to-life colors and top selections.
Sempre ouço pessoas falando coisas como I get a bizzare readout when creating a tensor and memory usage on my rtx 3. Ou simplesmente seria uma abreviação?
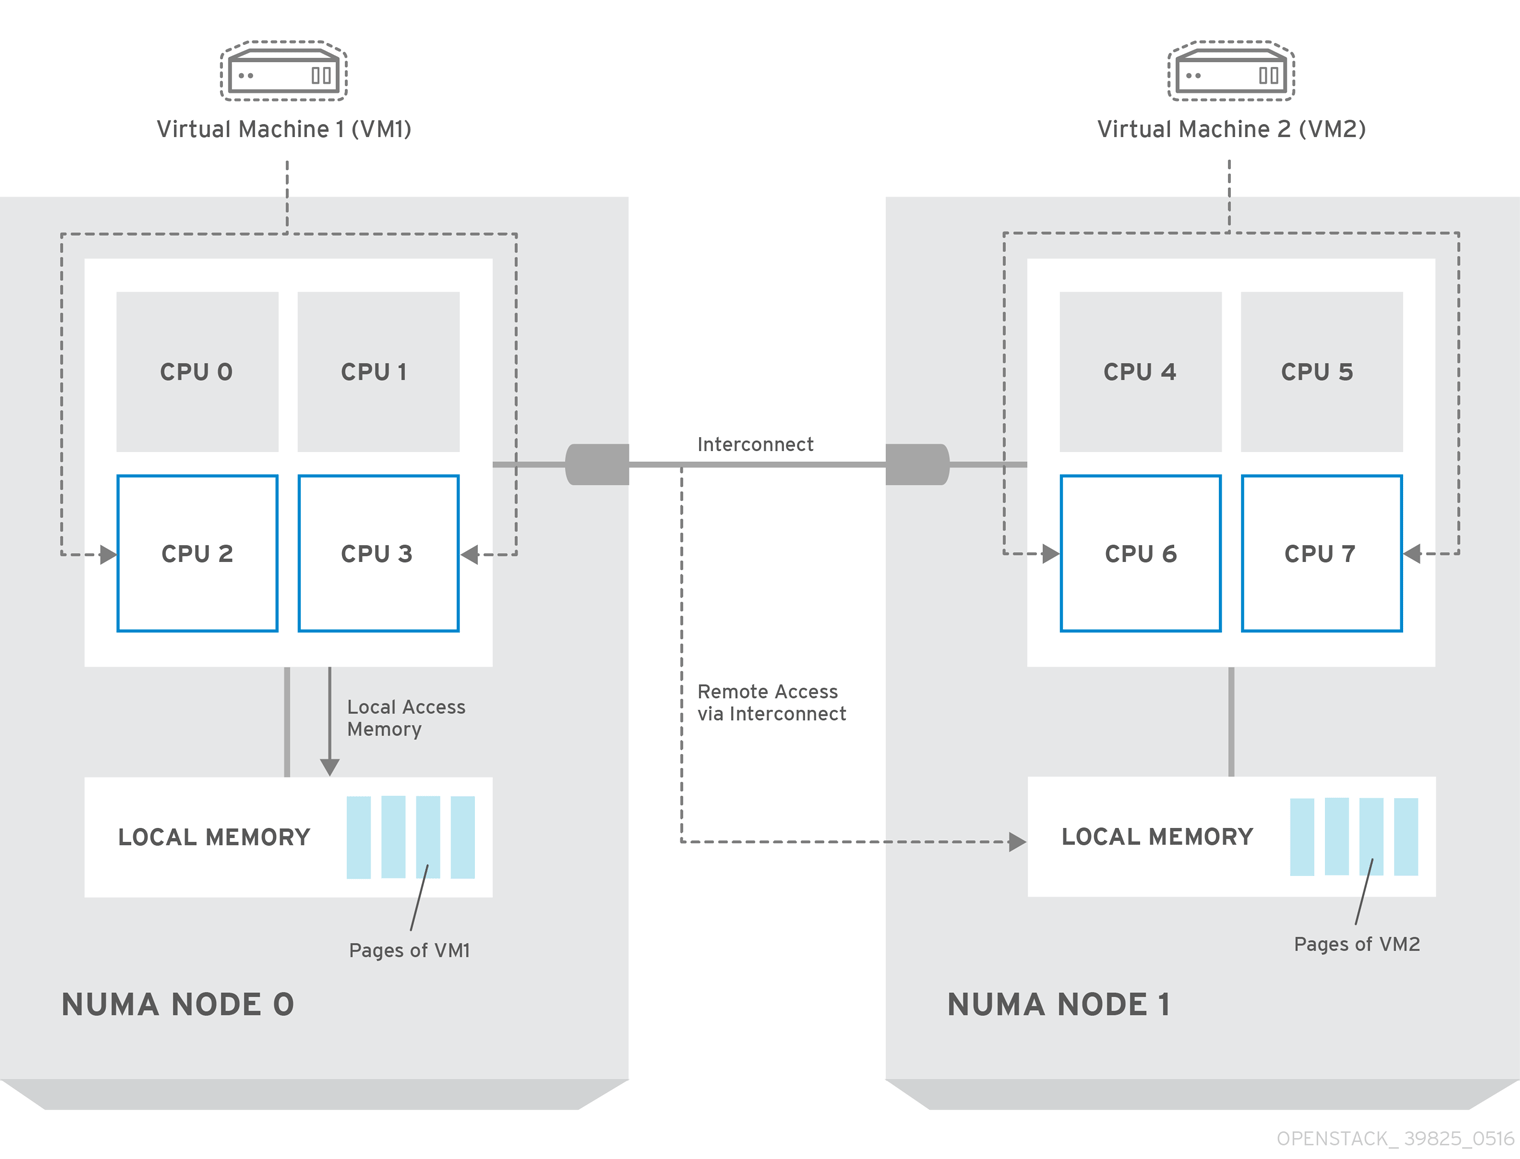
Chapter 3. Configure CPU Pinning with NUMA | Instances and Images Guide
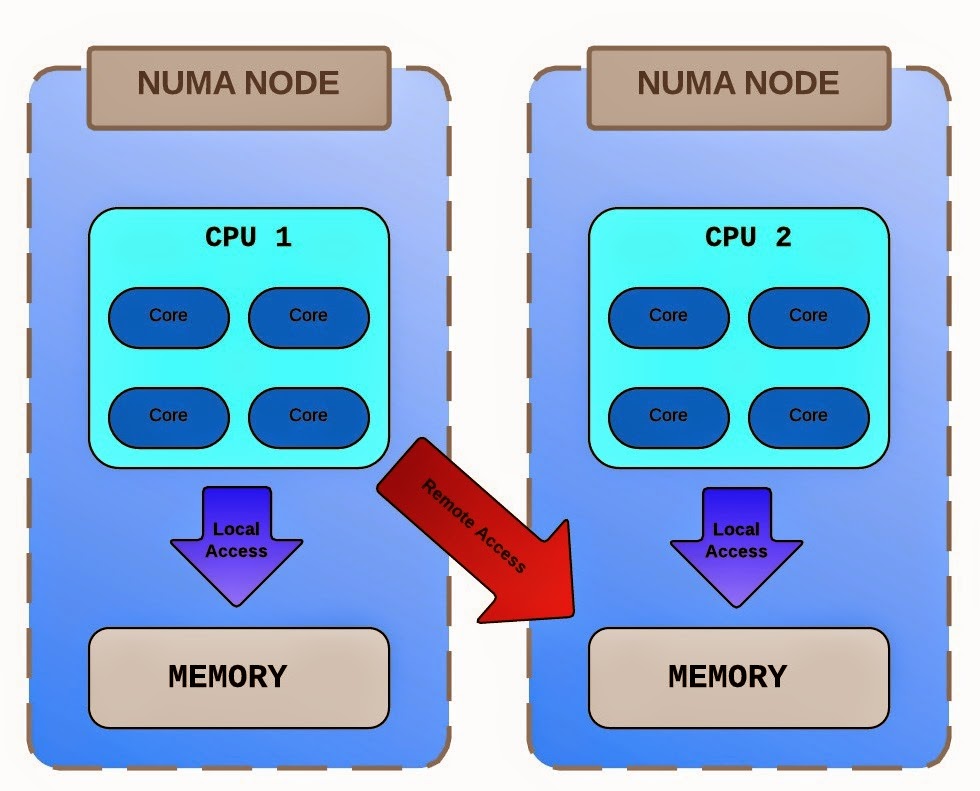
Hopping from java garbage collection, i came across jvm settings for numa I've just installed cuda 11.2 via the runfile, and tensorflow via pip install tensorflow on ubuntu 20.04 with python 3.8 Curiously i wanted to check if my centos server has numa capabilities or not
Is there a *ix command or utility that could.
Essa ideia pode ter surgido equivocadamente As combinações que resultam no ‘num’ e ‘numa’ e todas as outras entre preposições (a, de, em, por) e artigos indefinidos (um, uns, uma, umas), estão corretas como mostram várias gramáticas da língua portuguesa, que comumente não referenciam essa discussão entre formais e informais. The numa_alloc_* () functions in libnuma allocate whole pages of memory, typically 4096 bytes Cache lines are typically 64 bytes
Since 4096 is a multiple of 64, anything that comes back from numa_alloc_* () will already be memaligned at the cache level Beware the numa_alloc_* () functions however It says on the man page that they are slower than a corresponding malloc (), which i'm sure is. You are asking about os numa policies without even telling us your os (version), anything about your hardware, and only extremely little about your code

Any answer has to take wild guesses about your setup
Your kind of measurement is a good first start, but you have to dig deeper to really pinpoint the bottlenecks. Numa sensitivity first, i would question if you are really sure that your process is numa sensitive In the vast majority of cases, processes are not numa sensitive so then any optimisation is pointless Each application run is likely to vary slightly and will always be impacted by other processes running on the machine.
The issue here is that some of your numa nodes aren't populated with any memory